mirpy#
Turn T- and B-cell receptor repertoires into fixed-length numeric vectors you can cluster, visualise, and hand to a machine-learning model – at the scale of one receptor, one repertoire, or a whole cohort.
mirpy implements TCREMP: each receptor is embedded by its alignment distances to a fixed set of prototype sequences, so Euclidean distance in embedding space approximates pairwise alignment distance. That turns a set of variable-length strings into a coordinate system, which is what every downstream method actually needs.
PyPI package mirpy-lib, import name mir. Pure Python; the heavy lifting is reused from
seqtree and
vdjtools.
Install, embed your first receptors, cluster them, and compare two repertoires. Start here.
Guides by task: clonotype embedding, density and enrichment, repertoire embedding, the digital donor, explainable readouts, neural codecs.
Export sample vectors, save a shared basis, and fit or reuse a sample rotation.
Every command and every flag for the mir console script.
Why the prototype embedding is a coordinate system, what the repertoire vector knows, and what distance between two repertoires means.
Six runnable notebooks. Start with the signature pipeline: a folder of AIRR files to one table you can join with your metadata.
Every term this documentation uses. The immunology and signature vocabularies are defined once, in vdjtools’ glossary, and linked from here.
Install#
pip install mirpy-lib
Optional extras, each for one job:
pip install "mirpy-lib[ann]"     # pynndescent: approximate neighbours at whole-repertoire scale
pip install "mirpy-lib[ml]"      # torch: the neural codecs and the learned set encoder
pip install "mirpy-lib[bench]"   # the benchmark harness and theory experiments
Three scales#
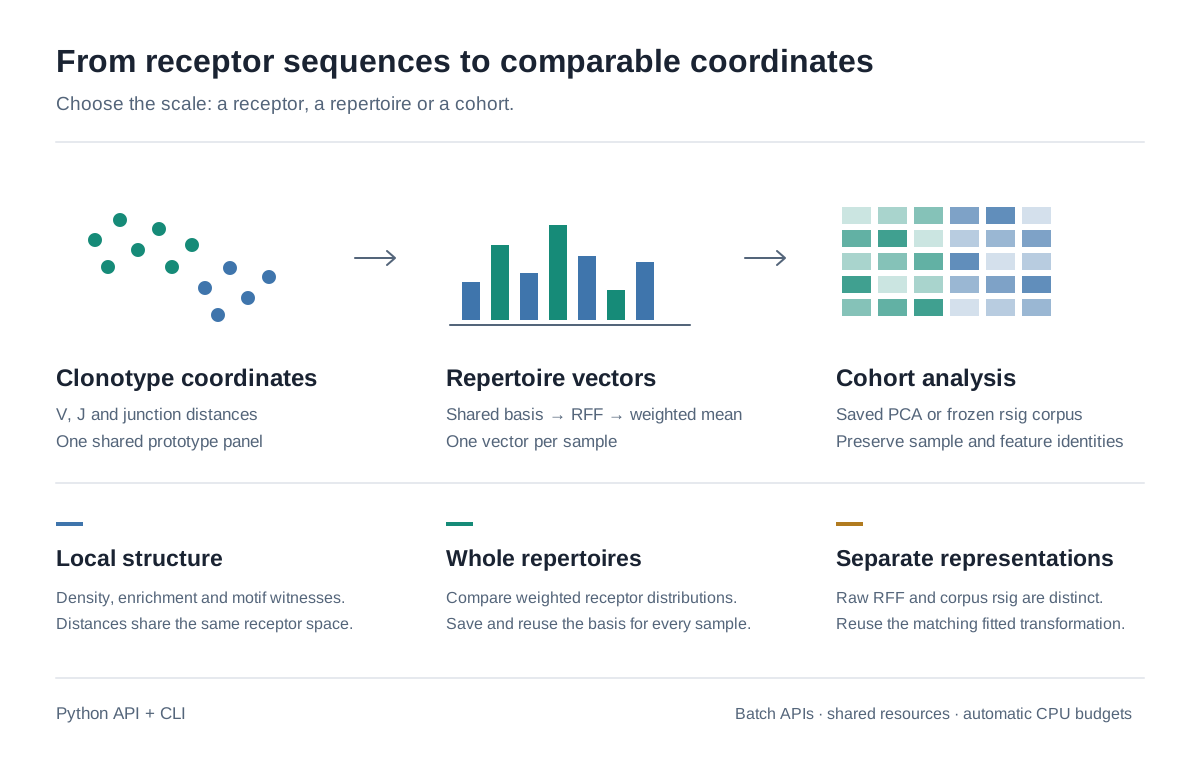
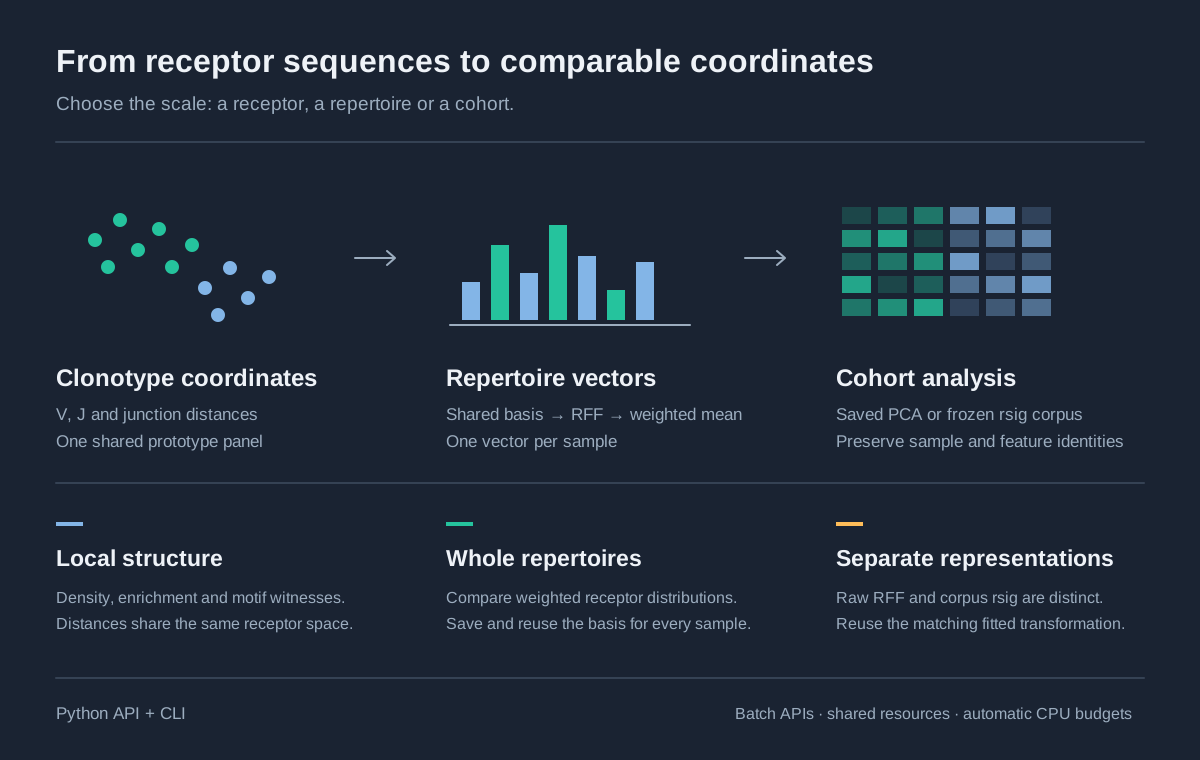
The three scales are the organising idea, and choosing the right one is most of the work:
Scale |
One unit is |
You get |
Module |
|---|---|---|---|
Clonotype |
one receptor |
a point in prototype space |
|
Repertoire |
one sample from one donor |
one fingerprint, |
|
Cohort |
many donors, several chains each |
one comparable matrix |
Your first embedding#
import mir                       # establish runtime limits first
import polars as pl
from mir.embedding.tcremp import TCREmp

model = TCREmp.from_defaults("human", "TRB")     # per-chain preset: 2000 prototypes
df = pl.DataFrame({
    "v_call":      ["TRBV10-3*01",   "TRBV20-1*01"],
    "j_call":      ["TRBJ2-7*01",    "TRBJ1-2*01"],
    "junction_aa": ["CASSIRSSYEQYF", "CSARVSGYYGYTF"],
})
X = model.embed(df)        # (2, 6000) float32 -- three distances per prototype
mir embed clonotypes  samples/*.tsv  -o clonotypes.tsv
mir embed repertoires cohort/*.tsv.gz -o sample_embeddings.tsv
mir pca sample_embeddings.tsv --fit rotation.npz -o sample_pcs.tsv
Each clonotype row interleaves V, J and junction distances for each prototype. The
junction part comes from seqtree.gapblock; the V and J parts are precomputed germline distances.
From a bag of receptors to one fingerprint#
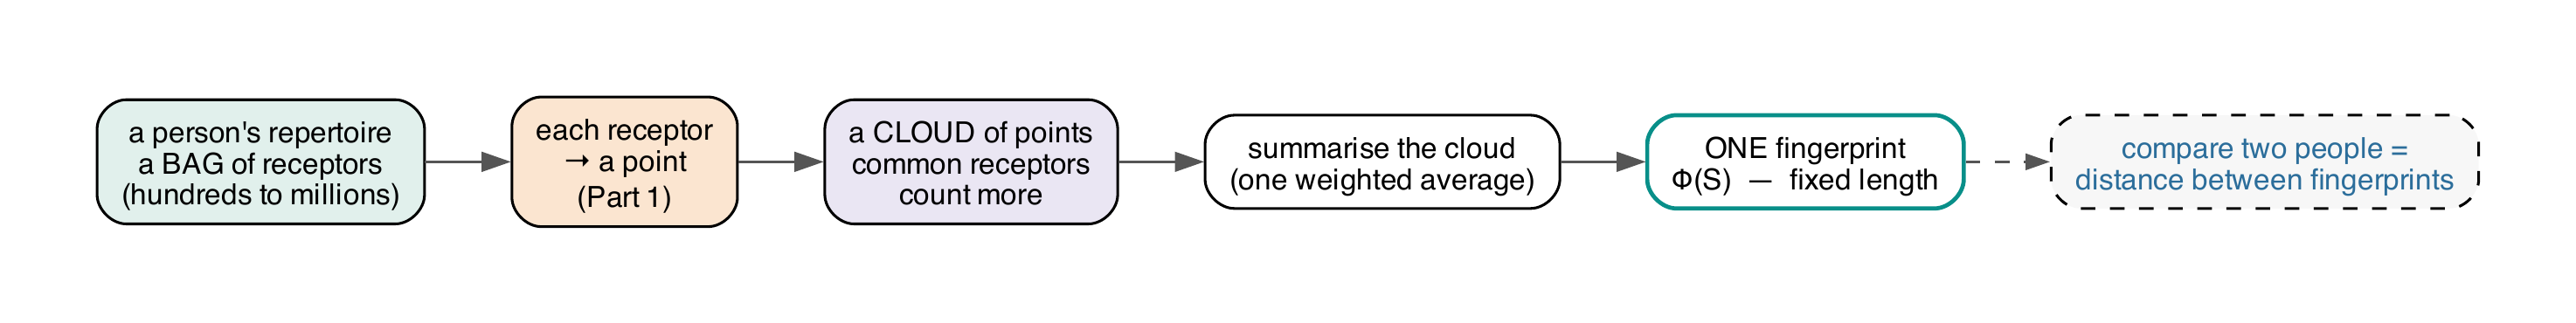
A repertoire is an unordered multiset of receptors with clone sizes, so its vector has to be
invariant to order and robust to depth. Phi(S) sketches it as a weighted cloud of points in three
blocks – a random-feature kernel mean, a Hill diversity profile (coverage-standardised
when an explicit target is supplied), and a
second-moment block carrying co-occurrence structure:
Clonotype and sample embeddings covers sample RFF export, shared basis fitting, saved rotations and the Python table API. User guide covers MMD and motif witnesses.
Important
Every sample in a cohort must be embedded through one prototype set and one basis, or the
distances are not comparable. fit_repertoire_space fits that basis once, and every container
refuses a prototype-hash mismatch rather than silently mixing two coordinate systems. Use
unbiased=True whenever samples differ in depth: the biased estimator’s self-term inflates
low-diversity samples and can manufacture a signal.
Choose your path#
You want to |
Go to |
|---|---|
Embed receptors and cluster antigen-specific ones |
|
Choose a prototype count and a PCA dimension |
|
Find enriched or antigen-driven neighbourhoods |
|
Export sample RFF vectors and fit or reuse PCA |
|
Compare whole repertoires rather than clonotypes |
|
Get one fixed, named feature vector per sample |
|
Name which part of a vector carries a signal |
|
Understand why any of this is valid |
|
Look up a command or a function |
|
Check what a term means |
Citing#
Cite this repository. The theory this implements is collected in Mathematical foundations, and the derivations and recorded benchmark numbers live in the companion analysis repository and manuscript appendix.
ISALGO LAB Academic and Non-Commercial Research License v1.0. See LICENSE.
The classical v1.x/v2 repertoire toolkit – parsing, overlap, diversity,
TCRnet, GLIPH – is frozen on the legacy-v2 branch (mirpy-lib 2.x); its functionality lives
on in vdjtools and
vdjmatch.